Someone watching your platform, so your team can build instead of firefight.
Monthly operations for cloud and bare-metal estates: monitoring and alerting, patching, backups you have actually restored, certificate and DNS hygiene, and a named engineer when something breaks.
What this solves
You hear about outages from customers
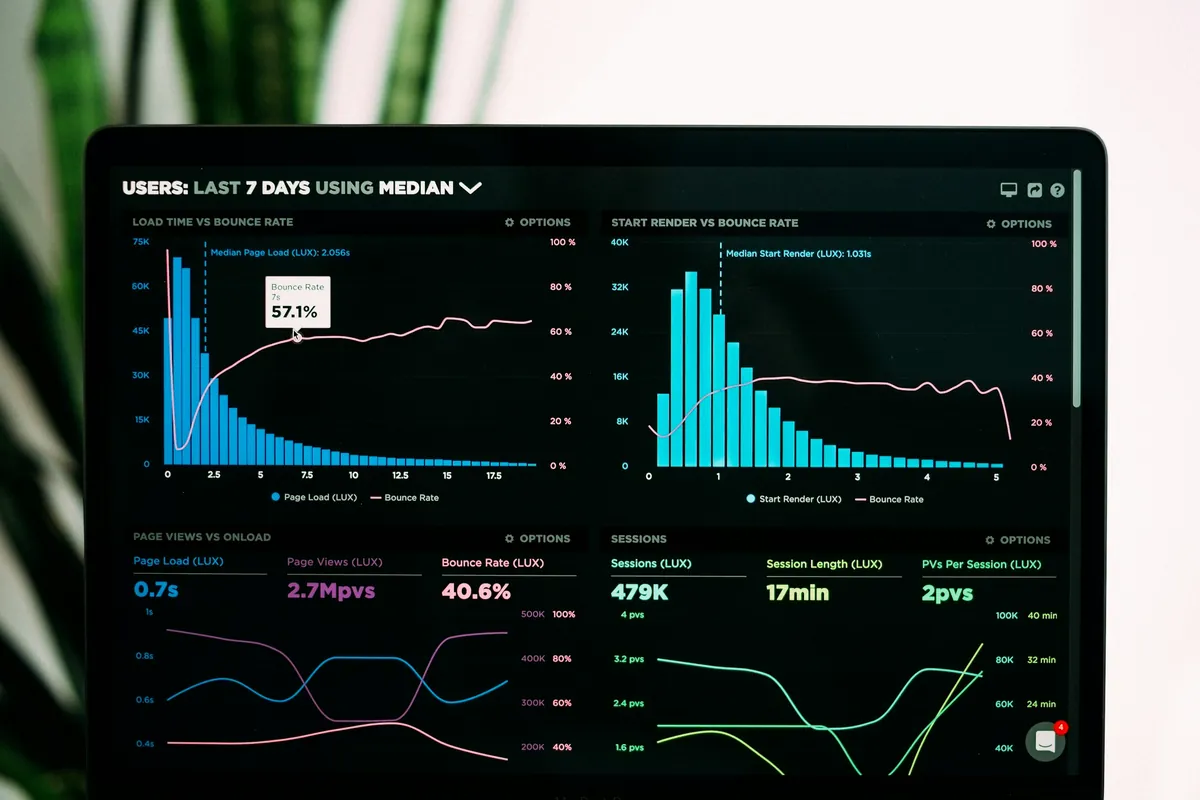
We put dashboards and alerts on what actually fails: health checks, errors, queues, certificates and backups.
Certificates expire without warning
Expired TLS certificates take sites down. We automate renewal and watch every endpoint.
Screens are slow and nobody knows why
We trace slowness end to end and fix it at the right layer.
The boring work never happens
Patching, end-of-life upgrades, backups and access reviews run on a schedule with a monthly report.
What you get
- Dashboards in Grafana or CloudWatch for infrastructure, applications and security findings, defined through the Grafana API so they can be rebuilt from code
- Alerts on the failures that matter to the business, such as a transaction that could not be saved, with an audible alarm on the operations screen
- Alert routing with written escalation steps
- Monthly patching and end-of-life planning
- Backup checks including restore tests
- Incident handling with a written report
- A plain-language monthly operations report
Ways to work with us
- Monthly retainer for business-hours cover
- Extended cover for critical systems [CONFIRM COVER HOURS]
- One-off observability set-up
- Review of a past outage
How the work runs
Onboard
Read access first; we map systems and agree what matters most.
Instrument
We add the monitoring that is missing and remove noisy alerts.
Operate
Alerts, patches, renewals and changes under an agreed process.
Report
A monthly report and a short review call.
What changed when we did this work
Fixed a cross-service N+1 lookup and moved aggregation into SQL.
An API that ignored page size was fixed, so the screen stopped making dozens of calls.
Prometheus and Grafana with custom exporters, hardened Docker hosts and zero-downtime deploys.
Tools we work with
- Grafana
- Prometheus
- Amazon CloudWatch
- Sentry
- GuardDuty
- EventBridge
- OpenSearch
- cert-manager
- Cloudflare
- Rancher
- AWS Backup
How is this different from cloud engineering?
Cloud engineering builds or migrates the platform. Managed operations keeps it healthy every month afterwards.
Do you offer 24/7 support?
Cover hours are agreed per client in writing. [STATE STANDARD COVER HOURS AND RESPONSE TIMES]
Do we have to give you full admin access?
No. We start read-only and request specific permissions for specific changes, reviewed regularly.
Can you take over a platform someone else built?
Yes. We start with an assessment and a stabilisation plan before taking on day-to-day operations.
Tell us what you are running today.
Send a short note about your systems and what is getting in the way. You will hear back from the engineer who would do the work.